Our mission
Measure what the work actually needs
Technical hiring has two breakdowns we want to solve.
The first is that coding tests have collapsed into a cheating arms race: capable AI agents and screen overlays make take-homes and live-coding screens trivial to pass without exercising the underlying skill. The second is that the capability that does matter, engineering effectiveness when working alongside AI, is not measured anywhere.
Banning AI from the interview selects for unaided coding while leaving the AI-orchestration skill entirely untested. We do something different. We give every candidate a unique conversation built from their own CV, then put them in a real codebase alongside the AI tool of their choice and watch how they ship.
We do not believe AI should make the hiring decision. We believe AI should produce evidence that is quote-grounded, auditable, and fair, so the human interviewer can make a better one.
What we’re building
Two products, one rubric
However you run your process, Basanite plugs in. Hand a round to the agent, or keep your own interviewers and let the co-pilot ride along.
Basanite agent
Runs a hiring round for you.
An adaptive voice interview built from each candidate’s own CV, followed by a written, quote-grounded briefing on their strengths, limits, and technical depth before you ever meet them. Round two puts them in the AI Collaboration Workbench: a sandboxed VS Code environment where they ship a real ticket alongside the AI tool of their choice.
Basanite co-pilot
Sits with your interviewers, live.
In your own rounds, the co-pilot suggests what to probe next in real time, then writes up the session and ranks each candidate with the evidence attached. Your interviewers stay in control; the note-taking and the scoring rigour come for free.
Both are grounded in the same eight metacognitive dimensions and scored on one rubric, every time, so every candidate is read the same way and every number opens to the quote behind it. See the methodology
What we believe
Four principles behind the product
Depth over breadth
Each layer of the assessment exists to move one level deeper into signal quality. A candidate who answers fluently at the surface should encounter ground that shifts beneath them at the next layer. The edges of real ability are blurry; performed ability has no edges.
Structure as fairness
By anchoring every evaluation to consistent frameworks and explicit scoring criteria, a self-taught engineer without institutional pedigree can be seen as clearly as one from a target university. Both are asked the same questions in the same spirit, with the same depth of follow-up.
Honest about AI limits
We flag where human expertise is required, produce quotable evidence rather than opaque scores, and position Basanite as infrastructure that makes human judgement better, not the mechanism that replaces it.
A two-way mirror
The best hiring processes leave candidates with a clearer understanding of themselves. Every assessment strategy deployed by Basanite can be honestly explained to the candidate it is applied to.
The team
Built by people who felt the problem
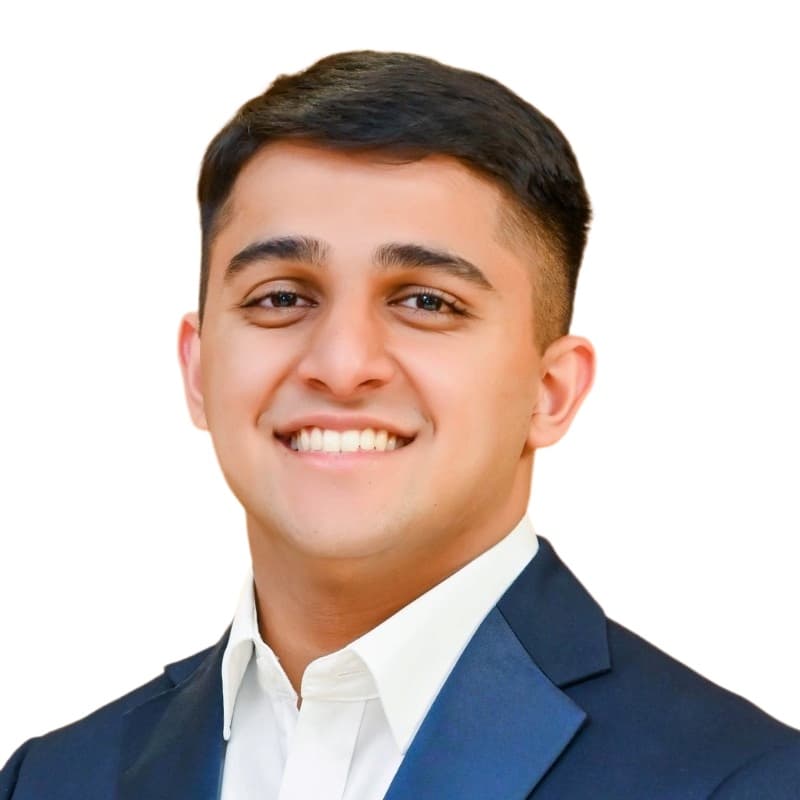
Aditya Shah
CEO
Owns commercial, fundraising, customer discovery and positioning. Has lived the candidate side of the broken hiring funnel first-hand.
- ◆Data Analyst & Technology Modeller at Virgin Media O2 (13-month placement)
- ◆Previously founded an edtech startup
- ◆Final-year Computer Science, University of Manchester
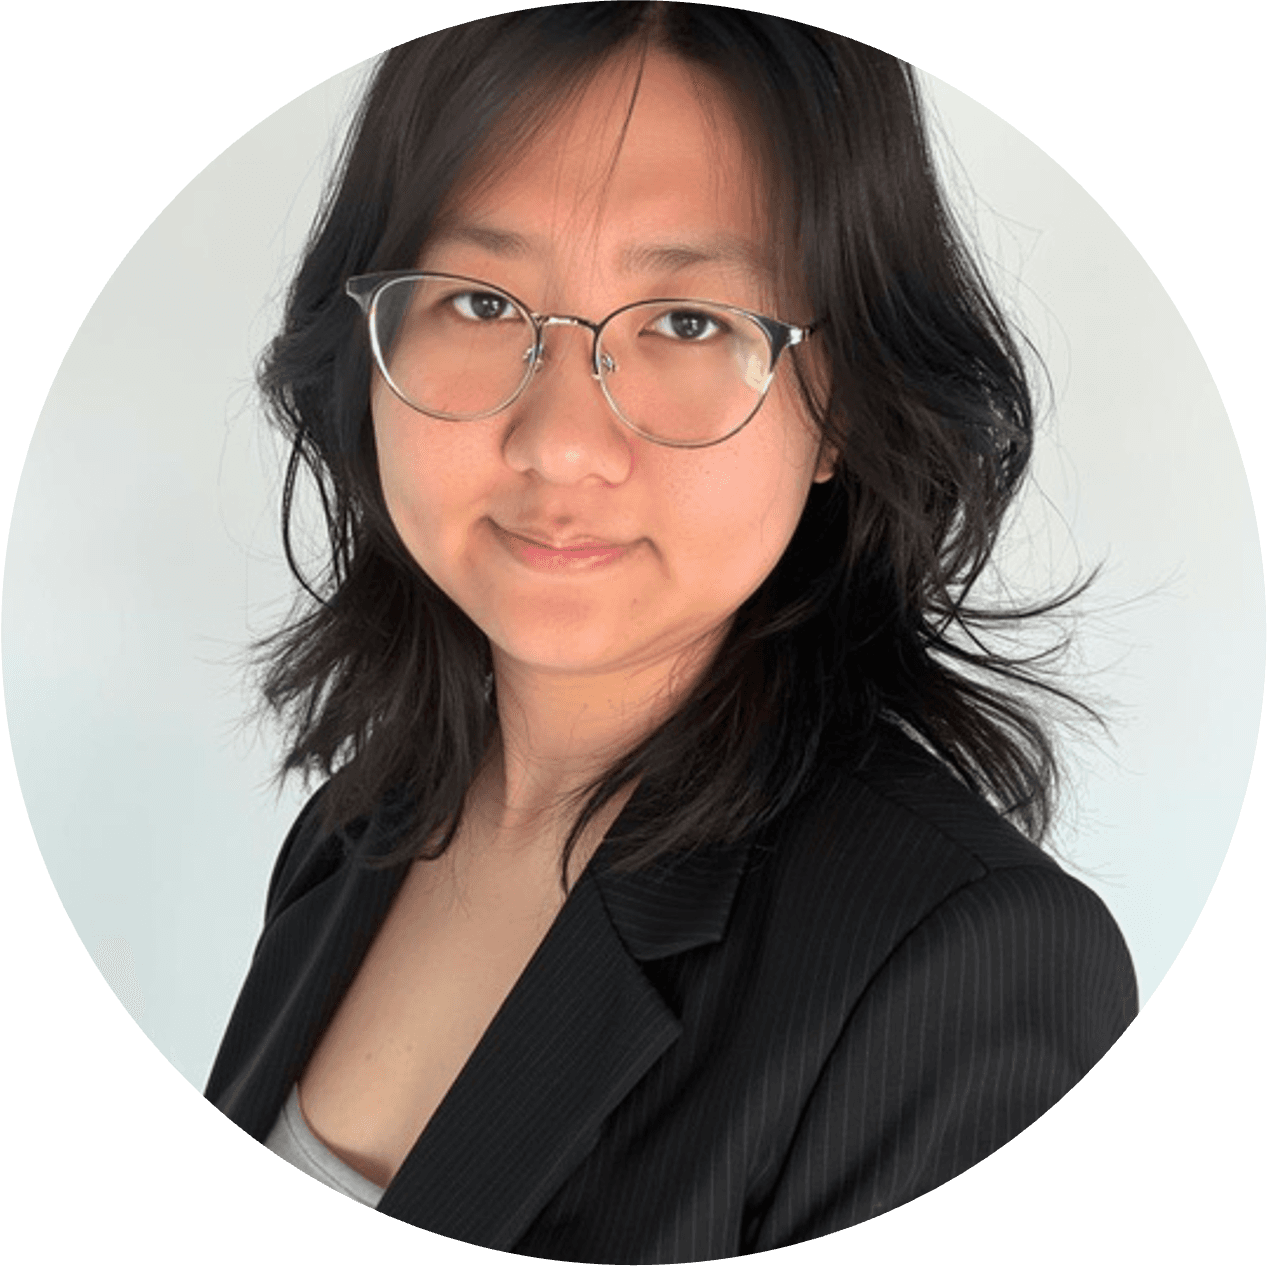
Lynn Zhao
CPO
Owns product, primary research with hiring managers and occupational psychometricians, and the prompt architecture behind the interview agent.
- ◆BSc Artificial Intelligence, University of Manchester
- ◆AI Safety Fellowship at BlueDot Impact, prior internship at OpenAI Cambridge
- ◆UniHack 2025 Digital CleanUp, 1st place